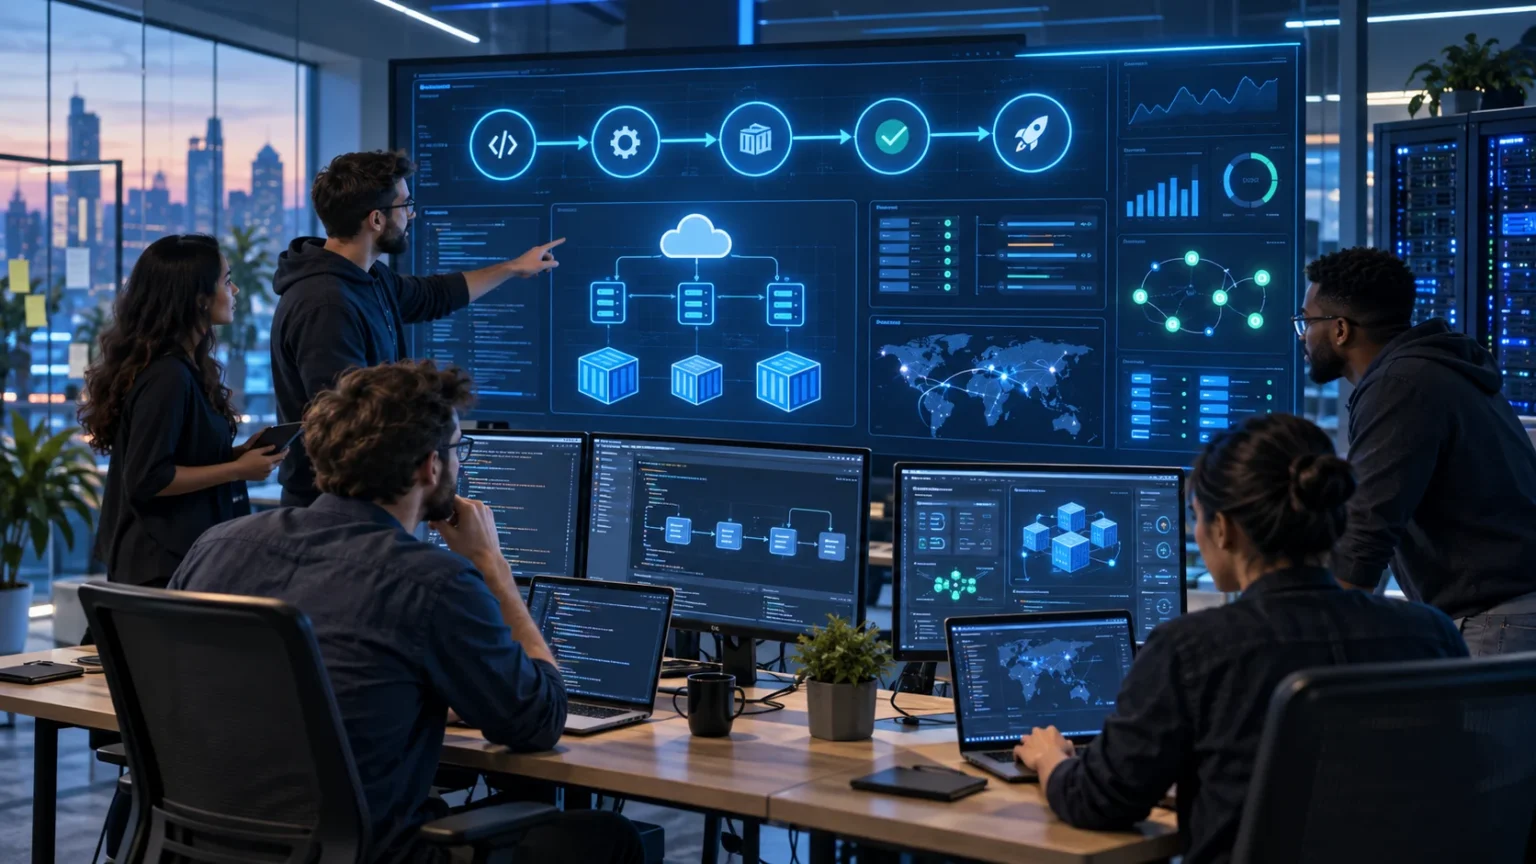

Modern software teams need more than talented developers to release applications quickly and reliably. They also need tools that help automate testing, deployment, infrastructure management, monitoring, collaboration, security, and version control. The right DevOps toolchain can reduce manual work, improve consistency, and make software delivery easier to manage across development and operations teams.
Choosing the best DevOps tools does not mean installing every popular platform available. Each team has different infrastructure, programming languages, cloud environments, security requirements, and deployment workflows. The goal is to build a practical technology stack that supports automation and collaboration without introducing unnecessary complexity or overlapping tools.
What Are DevOps Tools?
DevOps tools are software platforms that support different stages of the software development and operations lifecycle. They can help teams plan work, manage source code, automate builds, run tests, deploy applications, configure infrastructure, monitor performance, and respond to problems. Together, these technologies make software delivery more consistent and repeatable.
Most organizations use several tools rather than relying on a single DevOps platform. A team might use GitHub for source control, Jenkins for automation, Docker for containers, Kubernetes for orchestration, Terraform for infrastructure, and a monitoring platform for observability. The exact combination depends on how applications are designed and deployed.
Tools work best when they support strong DevOps practices rather than becoming a substitute for them. Automation cannot fix poor communication or unclear responsibilities by itself. Teams need shared ownership, reliable processes, and measurable goals before technology can deliver its full value.
GitHub: Best for Source Code Collaboration
GitHub is one of the most widely used platforms for managing source code with Git. Development teams can store repositories, track changes, review pull requests, manage issues, and collaborate on software from one central environment. This makes it easier for developers to understand what changed, who made the change, and why.
GitHub also supports automation through workflows that can build, test, and deploy applications when specific events occur. For example, a new code commit can trigger automated tests before the change is approved. This helps teams catch problems earlier and reduces the amount of repetitive manual work involved in software delivery.
GitHub is particularly useful for organizations wanting source control and automation within the same ecosystem. Small teams can start with basic repositories, while larger companies can introduce permissions, branch protection, code reviews, security scanning, and automated pipelines. Its broad developer ecosystem also makes integration with other DevOps technologies relatively straightforward.
GitLab: Best All-in-One DevOps Platform
GitLab combines source code management with CI/CD, issue tracking, security features, deployment workflows, and other DevOps capabilities. Instead of connecting many separate services, teams can manage large portions of the software lifecycle within one platform. This can reduce tool fragmentation for organizations that prefer a more integrated environment.
Its built-in pipelines allow developers to define how code should be built, tested, checked, and deployed automatically. Teams can create different stages for development, testing, staging, and production. This provides a repeatable workflow and helps reduce inconsistencies that can occur when releases depend heavily on manual commands.
GitLab can be attractive to organizations wanting strong control over their DevOps environment and fewer disconnected platforms. However, teams should still evaluate whether they genuinely need all available features. An all-in-one solution can simplify integration, but it can also become complicated if employees are expected to use capabilities that provide little practical value.
Jenkins: Best for Flexible CI/CD Automation
Jenkins is a popular automation server commonly used for continuous integration and continuous delivery workflows. Teams can configure pipelines that automatically build applications, run tests, package software, and trigger deployments. Its flexibility has made it a long-standing choice for organizations with customized development and release processes.
A major strength of Jenkins is its extensive plugin ecosystem. Teams can connect it with source control systems, container platforms, testing frameworks, cloud providers, notification tools, and infrastructure automation software. This makes Jenkins highly adaptable when organizations need pipelines that involve several different technologies.
The flexibility can also create management overhead. Jenkins environments with large numbers of plugins and custom pipelines may require ongoing maintenance and careful upgrades. Teams should keep pipeline configurations organized, document important automation, and avoid installing unnecessary plugins simply because they are available.
Docker: Best for Containerized Applications
Docker allows developers to package applications and their dependencies into containers that can run consistently across compatible environments. This reduces the classic problem where software works on one machine but behaves differently somewhere else. Teams can define application environments once and use them across development, testing, and production.
Containerization fits naturally into DevOps because Docker images can move through automated pipelines. A CI/CD process can build an image, run tests, scan it for vulnerabilities, and then deploy the approved version. This makes application releases more predictable than manually configuring software on individual servers.
Docker is particularly useful for microservices, APIs, web applications, development environments, and modern cloud workloads. However, containers still require secure images, networking, storage, monitoring, and lifecycle management. Teams running large container environments usually need orchestration or additional management tools rather than relying entirely on individual Docker commands.
Kubernetes: Best for Container Orchestration
Kubernetes helps teams manage containerized applications across clusters of servers. It can schedule workloads, restart failed containers, distribute traffic, scale applications, and coordinate updates automatically. This makes it valuable when organizations operate more containers than engineers can realistically manage through individual manual commands.
Development teams define how applications should run, and Kubernetes continuously works toward that desired state. If a container fails, it can create a replacement. If demand grows, teams can increase the number of application replicas or configure automatic scaling to respond to changing workload requirements.
Kubernetes is powerful but introduces considerable complexity. Smaller applications may not need clusters, orchestration policies, advanced networking, and multiple supporting systems. It becomes most valuable when organizations already have significant container workloads and genuinely need automated scheduling, scaling, recovery, and application management across multiple machines.
Terraform: Best for Infrastructure as Code
Terraform helps teams create and manage infrastructure using configuration files rather than manually clicking through cloud dashboards. Engineers can define servers, networking, storage, databases, and other resources in code. These configurations can then be reviewed, versioned, and applied consistently across different infrastructure environments.
Infrastructure as Code improves repeatability because development, testing, and production environments can be created from documented configurations. Teams no longer need to rely entirely on administrators remembering how each resource was originally set up. Changes can be reviewed before implementation, reducing the risk of undocumented infrastructure modifications.
Terraform is especially useful for organizations managing cloud infrastructure across many environments or providers. However, infrastructure code still requires careful testing and access control. Automation can create incorrect infrastructure just as quickly as correct infrastructure, so teams should review changes and protect sensitive credentials before applying them.
Ansible: Best for Configuration Management
Ansible helps automate configuration management, software installation, system updates, and repetitive administrative tasks. Teams can define how servers should be configured and apply those instructions consistently across multiple machines. This reduces the need to log into individual servers and repeat the same setup commands manually.
The platform uses human-readable configuration files that describe desired tasks and system states. Administrators can automate package installation, application configuration, security settings, service management, and deployment steps. This is particularly useful in environments where many servers require similar configurations but still need centralized management.
Ansible can complement Infrastructure as Code tools rather than replacing them. Terraform might create the infrastructure while Ansible configures software inside the resulting systems. Combining tools according to their strengths can produce cleaner automation than forcing one platform to handle every aspect of infrastructure provisioning and configuration.
Prometheus and Grafana: Best for Monitoring
Prometheus is commonly used to collect metrics from applications and infrastructure, while Grafana helps teams visualize operational data through dashboards. Together, they can provide visibility into application availability, response times, resource consumption, traffic, errors, and other performance indicators important to modern DevOps teams.
Monitoring allows teams to identify problems before users report them. Alerts can be configured when important metrics cross expected thresholds, such as unusually high CPU usage or increasing application errors. Engineers can then investigate the underlying issue and determine whether a recent deployment or infrastructure change contributed to the problem.
Dashboards should focus on meaningful information rather than displaying every available metric. Too many charts and alerts can create noise that makes genuine problems harder to identify. Effective monitoring should help teams understand application health, customer impact, and system behavior quickly when incidents occur.
Jira: Best for DevOps Work Management
Jira is widely used for planning development work, tracking tasks, managing bugs, and coordinating software projects. Teams can organize work into stories, issues, sprints, releases, and broader initiatives. This gives developers, operations teams, product managers, and other stakeholders a shared view of what is being worked on.
Although Jira does not deploy software or manage infrastructure directly, planning is an important part of DevOps. Teams need visibility into feature development, technical debt, incidents, security issues, and operational improvements. Connecting these activities helps prevent operations work from becoming separated from broader product development.
The platform is most effective when workflows remain understandable. Overly complicated boards, excessive ticket fields, and unnecessary approval stages can slow teams down rather than improve organization. DevOps teams should configure project management tools around useful workflows instead of forcing every process into highly detailed administrative structures.
How to Choose the Right DevOps Tools
Begin with the problem your team needs to solve rather than selecting tools based on popularity. Identify whether the biggest challenge involves slow builds, unreliable deployments, poor monitoring, inconsistent infrastructure, security gaps, or communication problems. A clear problem makes it easier to evaluate which platform can produce meaningful improvement.
Integration should also influence the decision. DevOps tools work together as part of a larger delivery pipeline, so source control, testing, CI/CD, containers, infrastructure, monitoring, and security platforms need reliable connections. A technically powerful tool can create unnecessary friction if it does not integrate well with the rest of the environment.
Finally, consider team skills, pricing, scalability, maintenance, and long-term support. A complex enterprise platform may offer hundreds of features but still be inappropriate for a small development team. The best DevOps tool is usually the one that solves an important problem while remaining understandable and manageable for the people who actually use it.
DevOps Tool Best Practices
Keep your toolchain as simple as possible. Adding another platform should solve a clear problem or significantly improve an existing process. Too many overlapping tools increase licensing costs, training requirements, integrations, notifications, credentials, and maintenance responsibilities without necessarily improving software delivery.
Standardize repeatable processes through code and automation wherever practical. CI/CD pipelines, infrastructure configurations, container definitions, and monitoring rules should be documented and stored in version control when appropriate. This creates transparency and makes important workflows easier to reproduce when employees or infrastructure change.
Measure whether the toolchain actually improves outcomes. Deployment frequency, recovery time, failure rates, application performance, security findings, and developer productivity can provide useful signals. DevOps success should be judged by software delivery and reliability rather than by the number of technologies included in the stack.
Conclusion
The best DevOps tools for modern teams support different parts of the software lifecycle, from source control and CI/CD to containers, infrastructure automation, monitoring, and project management. GitHub, GitLab, Jenkins, Docker, Kubernetes, Terraform, Ansible, Prometheus, Grafana, and Jira each solve different problems rather than competing for exactly the same role.
A strong DevOps stack does not require every tool mentioned above. Small teams may need only source control, automated testing, simple deployment, and monitoring, while enterprise environments may require sophisticated orchestration and infrastructure automation. Tool selection should always reflect the size, architecture, skills, and operational requirements of the organization.
Most importantly, tools should support collaboration and reliable processes rather than define DevOps by themselves. Start with clear delivery problems, automate repetitive work gradually, and choose technologies that integrate well. A simple, well-managed toolchain usually creates more value than a complicated stack filled with platforms the team rarely uses.
FAQs
What is the most important DevOps tool?
There is no single most important tool for every team. Source control is fundamental, but CI/CD, monitoring, infrastructure automation, and container tools become important depending on how applications are developed and deployed.
Which DevOps tools are best for beginners?
Beginners can start with GitHub for source control, a simple CI/CD workflow, Docker for learning containers, and basic monitoring tools. Adding technologies gradually makes the overall DevOps ecosystem easier to understand.
Is Docker a DevOps tool?
Yes. Docker is widely used in DevOps because it packages applications into consistent containers that can move through development, testing, and deployment pipelines with fewer environment-related differences.
Is Kubernetes necessary for DevOps?
No. Kubernetes is useful for orchestrating larger container environments, but many DevOps teams do not need it. Smaller applications can often be deployed successfully using simpler cloud, container, or platform services.
How many DevOps tools should a team use?
There is no ideal number. Teams should use enough tools to manage development, testing, deployment, infrastructure, monitoring, and security effectively without creating unnecessary overlap or excessive operational complexity.